Introduction: The Operational Challenge of Evolving Enterprise Systems
Modernizing or evolving an enterprise system—whether ERP, CRM, or a custom business platform—often triggers anxiety around potential downtime. For organizations with 24/7 operations or high transaction volumes, even brief interruptions can mean lost revenue, broken workflows, or regulatory issues. Yet, systems must evolve to support new business models, compliance, or technology standards. The challenge is clear: how do you upgrade or replace critical systems without halting business?
Why Zero Downtime Matters in Practice
Downtime is rarely just an IT inconvenience. In practice, it can:
- Disrupt customer service and order processing
- Delay financial transactions and reporting
- Break integrations with partners or logistics providers
- Trigger compliance violations if data is unavailable
- Undermine trust in IT and business leadership
For regulated industries, distributed teams, or organizations with global operations, the cost of downtime multiplies. This makes a zero-downtime evolution not just desirable, but often essential.
Main Approaches: Phased Rollout, Data Migration, and Module Replacement
Zero-downtime evolution is rarely achieved by a single leap. Instead, organizations rely on a combination of strategies. The most common are:
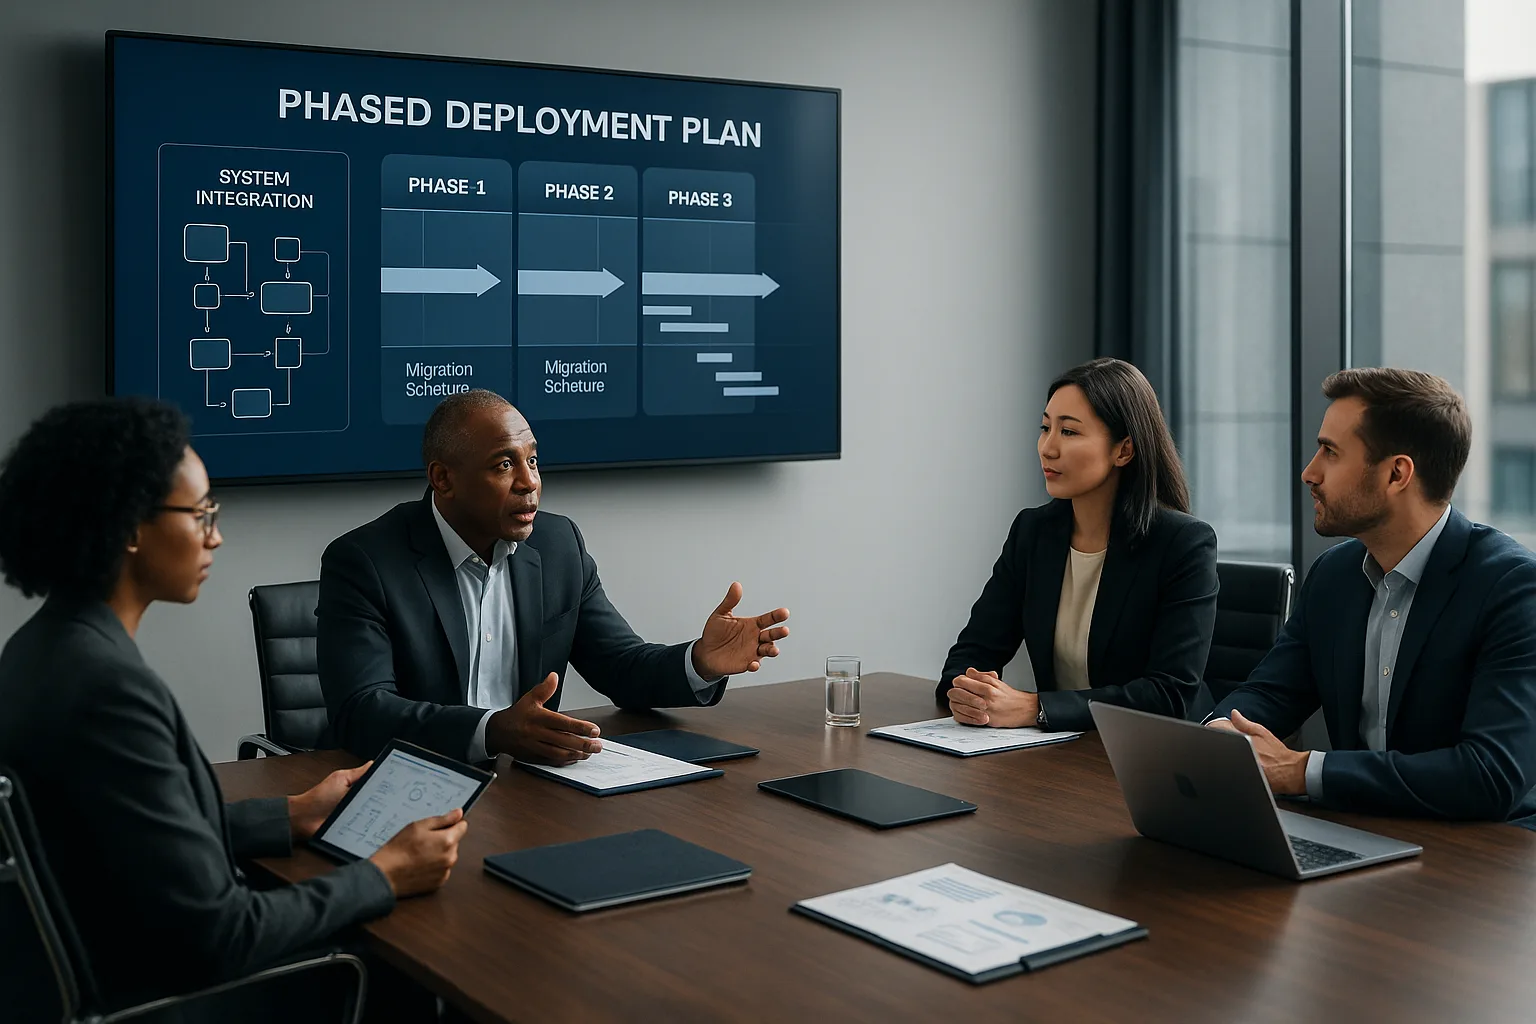
1. Phased Rollout
Instead of switching everything at once, new functionality is introduced in phases—by user group, geography, business unit, or process. This allows for controlled testing, feedback, and rollback if issues arise.
2. Parallel Run (Dual Operation)
The legacy and new systems run side by side for a period. Users or transactions are gradually migrated, and outputs are compared to ensure consistency. This approach is resource-intensive but reduces risk.
3. Incremental Module Replacement
Rather than replacing the entire system, individual modules (such as invoicing, inventory, or reporting) are swapped out one at a time. This minimizes disruption and allows for focused testing.
4. Real-Time Data Synchronization
During migration, data changes are synced between old and new systems to keep both up to date. This is critical for phased cutovers and parallel runs, but it adds complexity and requires robust integration.
5. Feature Flagging and Blue-Green Deployments
For web-based or cloud-native systems, feature flags and blue-green deployments allow teams to switch traffic between old and new versions instantly, enabling rapid rollback if issues arise.
| Approach | Best For | Risks | Operational Effort |
|---|---|---|---|
| Phased Rollout | Large, diverse user bases | Complex coordination, partial data consistency | Medium to high |
| Parallel Run | Critical operations, high risk tolerance | Resource intensive, potential data drift | High |
| Module Replacement | Modular architectures | Integration gaps, process misalignments | Medium |
| Data Synchronization | Transactional systems | Sync failures, latency issues | High |
| Blue-Green Deployment | Cloud/web platforms | Misrouted traffic, incomplete rollback | Low to medium |
Practical Implementation and Evaluation Criteria
Choosing and executing the right approach depends on several operational realities:
- System Architecture: Is the current system modular or monolithic? Modular systems are easier to evolve incrementally.
- Data Complexity: How many data sources, formats, and integrations are involved? Complex data requires rigorous mapping and reconciliation strategies.
- Business Criticality: Which processes must never be interrupted? Identify true “no downtime” zones versus areas where brief outages are acceptable.
- Integration Dependencies: What external systems, partners, or APIs must remain connected throughout the transition?
- Testing and Rollback: How will you validate correctness and performance at each stage? Is rollback feasible if issues are found?
- Change Management: How will you communicate with users, provide training, and support adoption during the transition?
For example, a phased rollout may be ideal for a multinational with region-specific workflows, while a blue-green deployment suits a SaaS provider with a unified global user base.
Common Mistakes and Warning Signs
- Underestimating Data Migration Complexity: Data mapping, cleansing, and reconciliation are often more challenging than anticipated. Incomplete or inconsistent data can break processes.
- Neglecting Integration Points: Overlooking how the new system interacts with third-party tools, legacy APIs, or partner platforms can lead to operational blind spots.
- Insufficient Testing: Skipping parallel run comparisons, user acceptance testing, or real-world simulations increases the risk of undetected issues post-launch.
- Poor Communication: Failing to prepare users for changes or provide clear rollback plans can erode trust and cause confusion during cutover.
- Lack of Monitoring and Rollback Capability: Not investing in real-time monitoring and rapid rollback mechanisms can turn minor glitches into major outages.
Conclusion: Next Steps for a Resilient System Evolution
Evolving an enterprise system without downtime is a multidisciplinary effort. Success depends on careful planning, granular risk assessment, and flexible execution. Start by mapping your operational landscape, identifying true “no-go” downtime windows, and selecting a migration strategy that fits your architecture and business priorities. Invest in robust data migration, integration testing, and user communication plans. Above all, treat zero-downtime evolution as an ongoing process, not a single event—continuous monitoring and incremental improvements will safeguard both business continuity and long-term agility.
If you’re considering a system evolution and want to explore practical options for your environment, a short consultation can clarify your best path forward.