Introduction: High Availability in the Real World
For modern businesses, web systems are often mission-critical. Downtime can mean lost revenue, eroded trust, or operational chaos. High availability (HA) architecture is not just a technical buzzword—it's a practical discipline that determines how reliably your business can operate online, serve customers, and integrate with partners. But achieving real HA goes far beyond buying redundant servers. It requires a layered approach, careful planning, and continuous operational awareness.
Why High Availability Matters for Business Web Systems
In practice, high availability is about minimizing service interruptions and ensuring that your web systems can tolerate failures—whether from hardware, software, or human error. This is especially vital for:
- Customer-facing portals where downtime directly impacts revenue or reputation
- Integrated B2B platforms that automate transactions and workflows
- Internal operations where outages can disrupt logistics, finance, or compliance
Business leaders and technical teams alike need to understand not just what can fail, but how failures are detected, contained, and recovered from—without creating new risks or operational complexity.
Core Components of High Availability Architecture
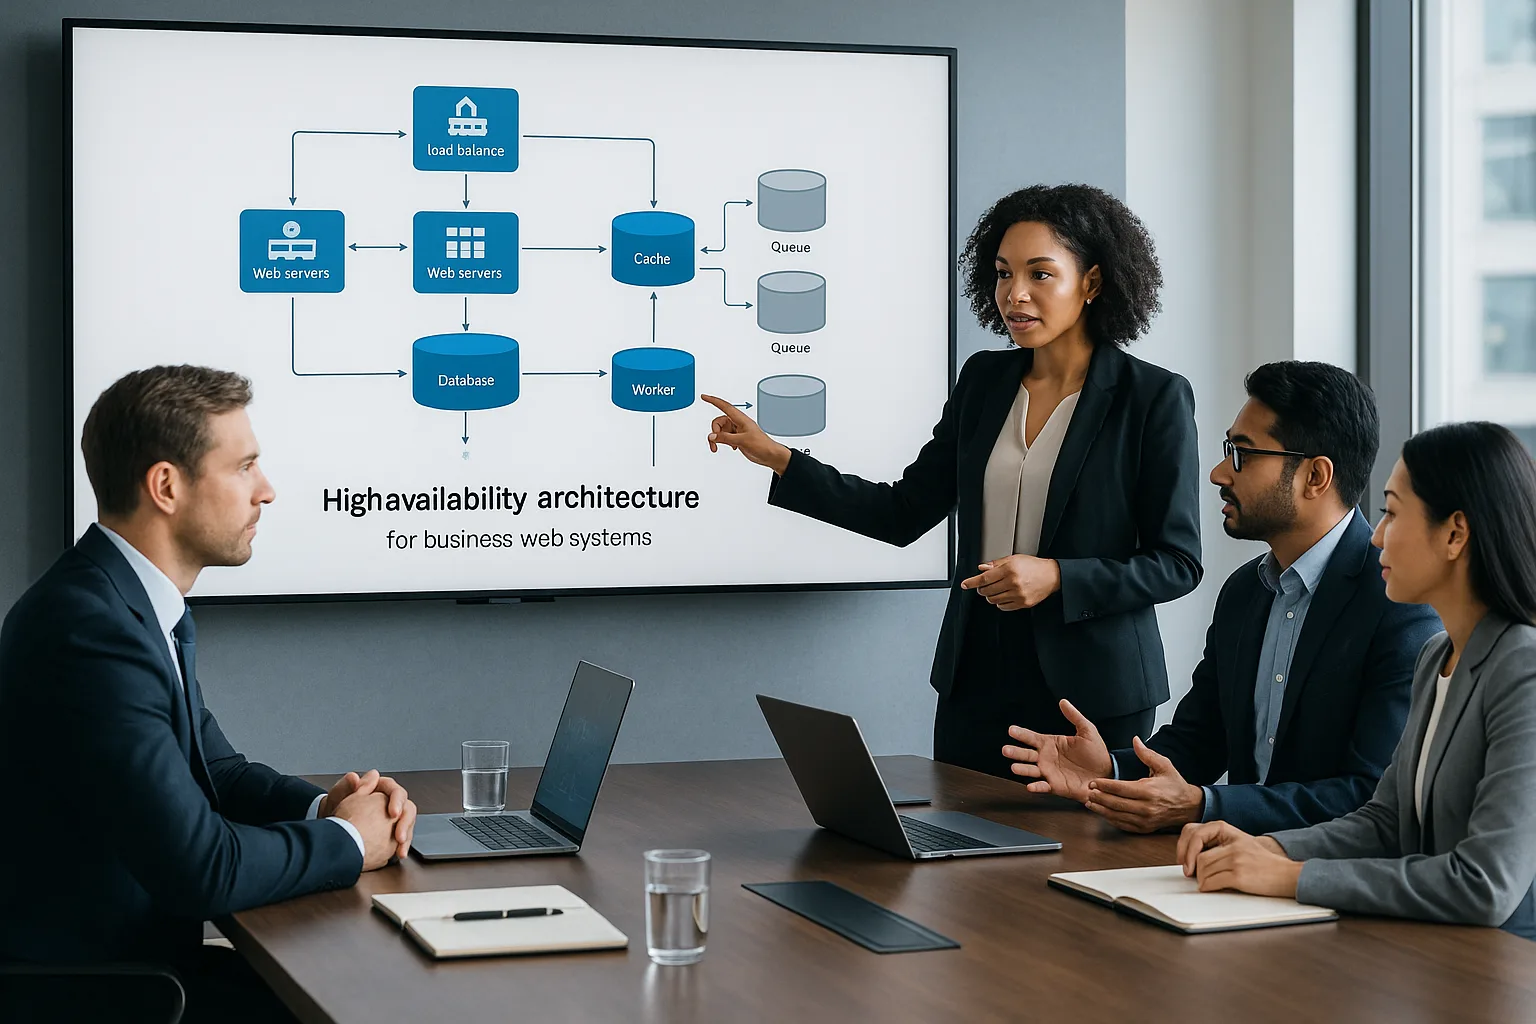
Effective HA architecture is built on several key pillars. Each addresses different failure modes and operational needs:
- Redundancy: Deploying multiple instances of critical components (servers, databases, network paths) so that no single failure brings down the system.
- Load Balancing: Distributing traffic and workload to avoid overloading any single node and to enable failover.
- Queues: Decoupling services with message queues (e.g., RabbitMQ, AWS SQS) to absorb spikes, buffer failures, and support asynchronous processing.
- Caching: Using distributed caches (e.g., Redis, Memcached) to reduce database load, speed up responses, and provide resilience against backend outages.
- Observability: Implementing robust logging, monitoring, tracing, and alerting to detect issues early and support rapid diagnosis.
- Rollout Safety: Introducing changes gradually (e.g., blue/green deployments, canary releases) to limit blast radius and enable fast rollback.
- Fault Isolation: Structuring systems so failures in one area don't cascade—using techniques like microservices, circuit breakers, and network segmentation.
Each of these components brings benefits, but also introduces new operational considerations, costs, and failure modes of its own.
Approaches, Trade-Offs, and Risks: What to Consider
There is no universal blueprint for HA—every business web system has unique requirements, constraints, and risk profiles. Consider these practical trade-offs:
| Component | Benefits | Risks/Trade-Offs | Operational Cost |
|---|---|---|---|
| Queues | Absorb spikes, decouple services, enable retries | Message loss, ordering issues, increased latency | Moderate (infrastructure, monitoring) |
| Caching | Faster response, reduced backend load | Stale data, cache invalidation bugs | Low to moderate (depends on scale) |
| Observability | Early detection, faster recovery | Alert fatigue, operational overhead | Moderate to high (tools, expertise) |
| Rollout Safety | Limits impact of bad deployments | Slower releases, more complex pipelines | Moderate (automation, process) |
| Fault Isolation | Limits scope of failures | Increased system complexity | High (design, testing) |
Choosing the right mix depends on your business's risk tolerance, technical maturity, and operational capacity. For example, a B2B portal handling sensitive transactions may require stricter isolation and observability than a marketing website. Overengineering for HA can also backfire, introducing complexity that itself becomes a source of outages.
Implementation Criteria: Building HA That Works
To design and operate a high-availability web system, consider these practical criteria:
- Define SLAs and SLOs: What level of uptime is truly required? Not all systems need five nines (99.999%).
- Assess Failure Domains: Map out where failures can occur (app servers, databases, network, third-party APIs) and how they can be isolated.
- Choose the Right Tools: Select queue, cache, and observability solutions that fit your scale, team expertise, and integration needs.
- Test for Failure: Regularly simulate outages (e.g., chaos engineering, failover drills) to validate your design and response playbooks.
- Automate Recovery: Where possible, automate failover, scaling, and rollback to minimize manual intervention during incidents.
- Monitor Both Health and Usage: Track not just uptime, but also latency, error rates, and queue/caching behavior to detect subtle degradation before it becomes an outage.
- Plan for Growth: Ensure your architecture can scale horizontally as load increases—without introducing new single points of failure.
Implementation is not a one-time event. High availability requires continuous review as your business, integrations, and usage patterns evolve.
Common Mistakes and Warning Signs
Even well-intentioned HA efforts can go off track. Watch for these warning signs:
- Assuming redundancy equals availability: Simply running two of everything doesn't guarantee uptime if both depend on a single misconfigured load balancer or shared database.
- Ignoring operational complexity: More moving parts (queues, caches, microservices) mean more things to monitor, patch, and troubleshoot.
- Poor observability: If you can't quickly answer "What failed, where, and why?", your HA design is incomplete.
- Unverified failover: If you haven't tested failover and recovery in production-like conditions, you can't trust it will work under real stress.
- Neglecting rollout safety: Deploying new code or configuration changes without guardrails is a leading cause of self-inflicted outages.
- Overlooking third-party dependencies: Your system is only as available as its weakest integration point—monitor and isolate them where possible.
Conclusion and Next Steps
Building high availability architecture for business web systems is both a technical and operational challenge. The right approach balances redundancy, decoupling, observability, and fault isolation with the realities of budget, team expertise, and business risk. There is no one-size-fits-all solution—but there are proven patterns and warning signs that can guide your journey.
If you're evaluating or planning HA improvements, start by mapping your failure domains, defining realistic SLAs, and investing in observability and rollout safety. Consider consulting with experienced partners to stress-test your design and operational practices.
For a deeper discussion or to explore tailored strategies for your environment, connect with our team for a consultative conversation—no pressure, just practical insight.